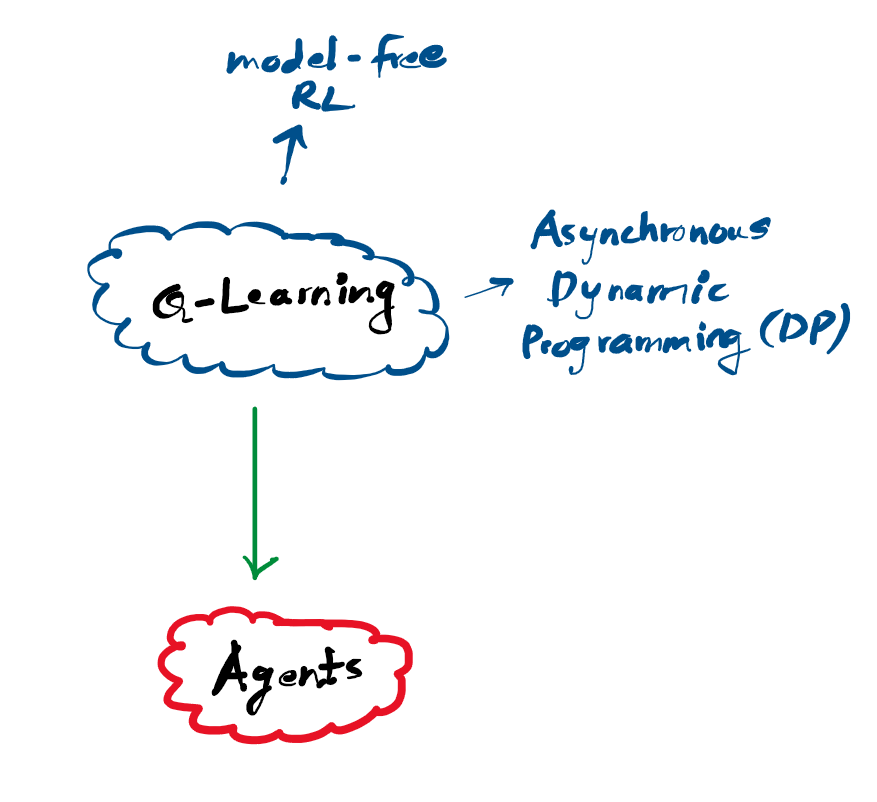
- Q-learning is model-free RL (Watkins, 1989) [1].
- It can also be viewed as method of asynchronous dynamic programming (DP) [1].
- It helps agents to learn to act optimally by experiencing all the results from sequence of actions taken [1].
How does Q-Learning work?
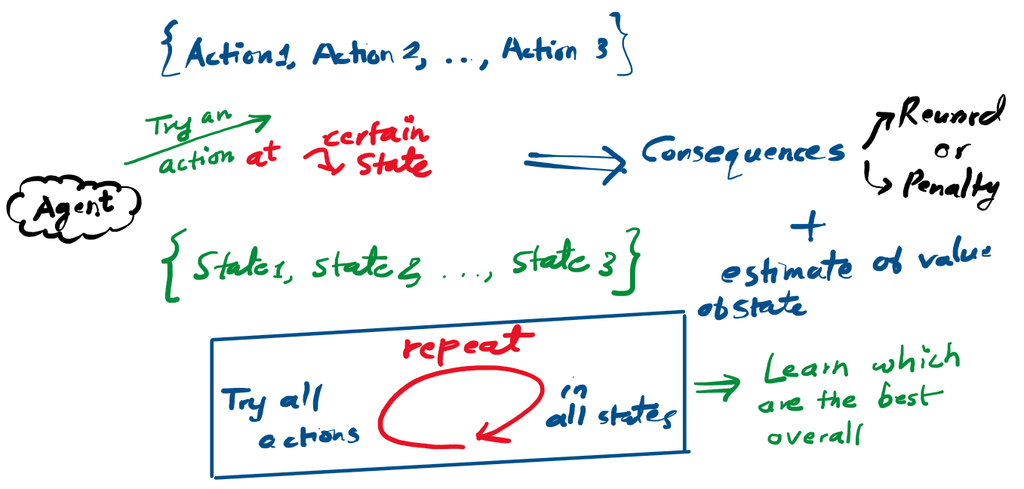
Learning in Q-Learning is similar to temporal differences (TD) [2] by Sutton. Steps involves (Found in paper [1] introduction section, second paragraph, Page 55).
- Agent takes action at a particular state.
- Agent evaluates its immediate reward or penalty as well as the state it is in.
- Agent tries all actions in all states repeatedly and leans the best overall based on long term discounted reward.
References:
- [1] C. J. C. H. Watkins and P. Dayan, “Q-learning,” Mach Learn, vol. 8, no. 3–4, pp. 279–292, May 1992, doi: 10.1007/BF00992698.
- [2] R. S. Sutton, “Learning to predict by the methods of temporal differences,” Mach Learn, vol. 3, no. 1, pp. 9–44, Aug. 1988, doi: 10.1007/BF00115009.